Multimodal AI Evaluation
Collecting 80,000+ LLM responses, evaluating data across 5 languages with 24/7 support.
Discover how DATAmundi delivered success for a Fortune 100 technology company.
LLM Evaluation at Scale for a Leading AI Research Organization
To conduct LLM performance evaluations to assess output quality across models in multiple languages and modalities, the client partnered with DATAmundi. The result was a successful, ongoing partnership with new LLMs launched and volumes continuing to grow
The Client
A leading AI research organization within a Fortune 100 technology company conducts ongoing large language model (LLM) performance evaluations to assess output quality across multiple models and configurations.
Their AI team operates without fixed schedules. Studies are triggered whenever a new model is released on the market. This requires a partner capable of delivering high-quality multimodal human evaluation on demand, often without advance notice.
DATAmundi has supported this LLM performance evaluation project for 1.5 years and growing – as part of a multi-year engagement with the client.
The Challenge
The client’s work required spontaneous delivery without advance notice. Each new LLM launch triggered evaluation studies with volumes fluctuating dramatically week to week, from 100 utterances to 10,000+. The work expanded from English-only to five language variants (English US/UK/Canadian, Spanish Mexican/US, and others), and from evaluation to include response collection across precise technical specifications.
The evaluation itself demanded a three-step assessment: response validity (does the answer address the question), accuracy (how complete and accurate it is), and fact-checking (verification of sources and regional appropriateness). The same query set went to five different annotators for majority consensus, requiring consistency across the entire annotation team. Any error in model version, response mode (text/voice/image), or regional settings would invalidate study results.
Our Approach
DATAmundi built a standing infrastructure designed for spontaneity and quality. We maintained dedicated teams of 10-12 specialized annotators per language who worked exclusively on this project. Each underwent comprehensive training on the three-step evaluation methodology, with our QC Lead simplifying complex technical guidelines into accessible modules.
We established 24/7 project management coverage across time zones. As one PM logged off, another took over, ensuring annotators always had immediate support for guideline questions or technical clarifications. Our standing pool of trained annotators allowed rapid scaling when volumes increased, with new annotators completing the same rigorous training before starting work.
DATAmundi’s AIDA Hub platform managed complex workflow requirements across different evaluation criteria, response modes, and language variants. Throughout the partnership, the client maintained a collaborative approach, working with us to refine guidelines rather than simply flagging issues, allowing continuous quality improvement.
The Results
The partnership has grown consistently with the client continuously increasing volumes. The rigorous three-step evaluation process was maintained consistently across all language variants and response modes (text, voice, and image).
As the client expanded their evaluation scope across models, languages, and response formats, DATAmundi’s infrastructure enabled rapid scaling without disrupting delivery timelines. Dedicated annotator teams, majority-consensus review, and 24/7 project management support ensured that evaluation quality remained consistent even as workloads fluctuated significantly between studies.
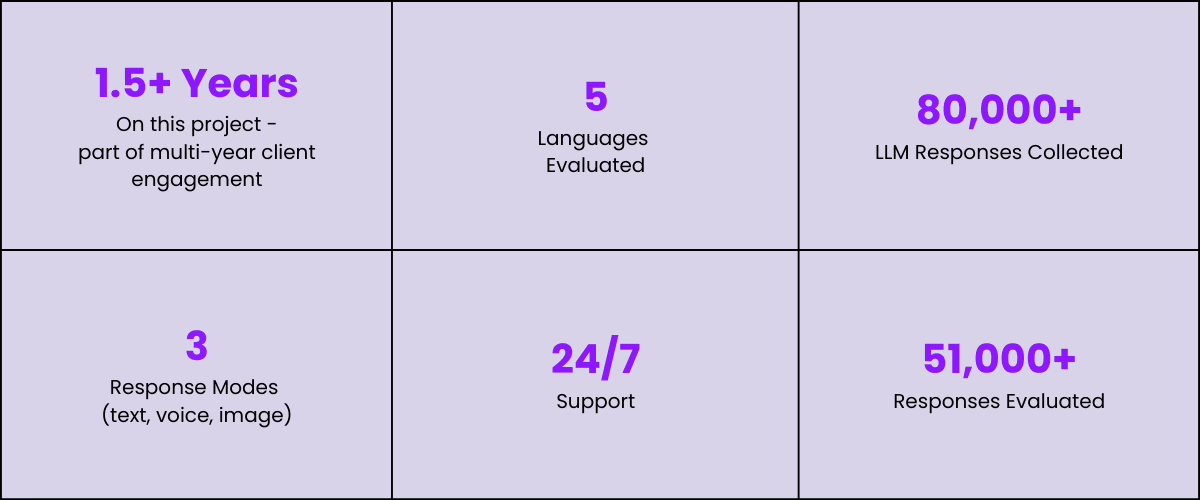
The following metrics summarize the scale and structure of the evaluation work delivered during the partnership.
Metric | Result |
| Partnership duration | 1.5+ years, ongoing |
| Languages evaluated | 5 (English US/UK/Canadian, Spanish Mexican, US) |
| Response modes evaluated | 3 (Text, Voice, Image) |
| Responses assessed | 50,000+ |
| Preference evaluations | 31,858 |
| Responses collected | 81,000+ |
| Annotators per language | 10-12 dedicated specialists |
| PM support coverage | 24/7 across time zones |
The Business Impact
The client received a reliable, expert-level LLM evaluation that supported their market research objectives. DATAmundi’s ability to deliver on spontaneous requests enabled their AI team to respond quickly to market developments.
The partnership expanded from English-only evaluation to five language variants and from evaluation-only to include response collection, demonstrating our ability to scale scope and complexity.
Launching a new LLM or evaluating model performance across markets?
Partner with DATAmundi for scalable, expert-level human evaluation across languages and response modes. Learn more about our AI Data Services or get in touch to discuss your project.