Building a high-performing AI model is one thing. Ensuring it performs reliably across different languages, domains, cultures and real-world scenarios is another.
DATAmundi delivers systematic evaluation of AI and LLM performance. We provide comprehensive benchmarking datasets and evaluation frameworks to measure accuracy and robustness across multiple criteria. Identifying misinformation, bias, and other vulnerabilities that impacts reliable performance.
Evaluate factual accuracy, quality, reasoning and robustness.
Bring expert human judgment into the evaluation process.
Identify performance gaps, safety risks and cultural biases.





Our global network of multilingual AI contributors and domain experts deliver scalable evaluation workflows embedded with human oversight, quality controls and actionable results.
Build confidence in your AI model’s performance. Across languages, modalities and real-world environments.
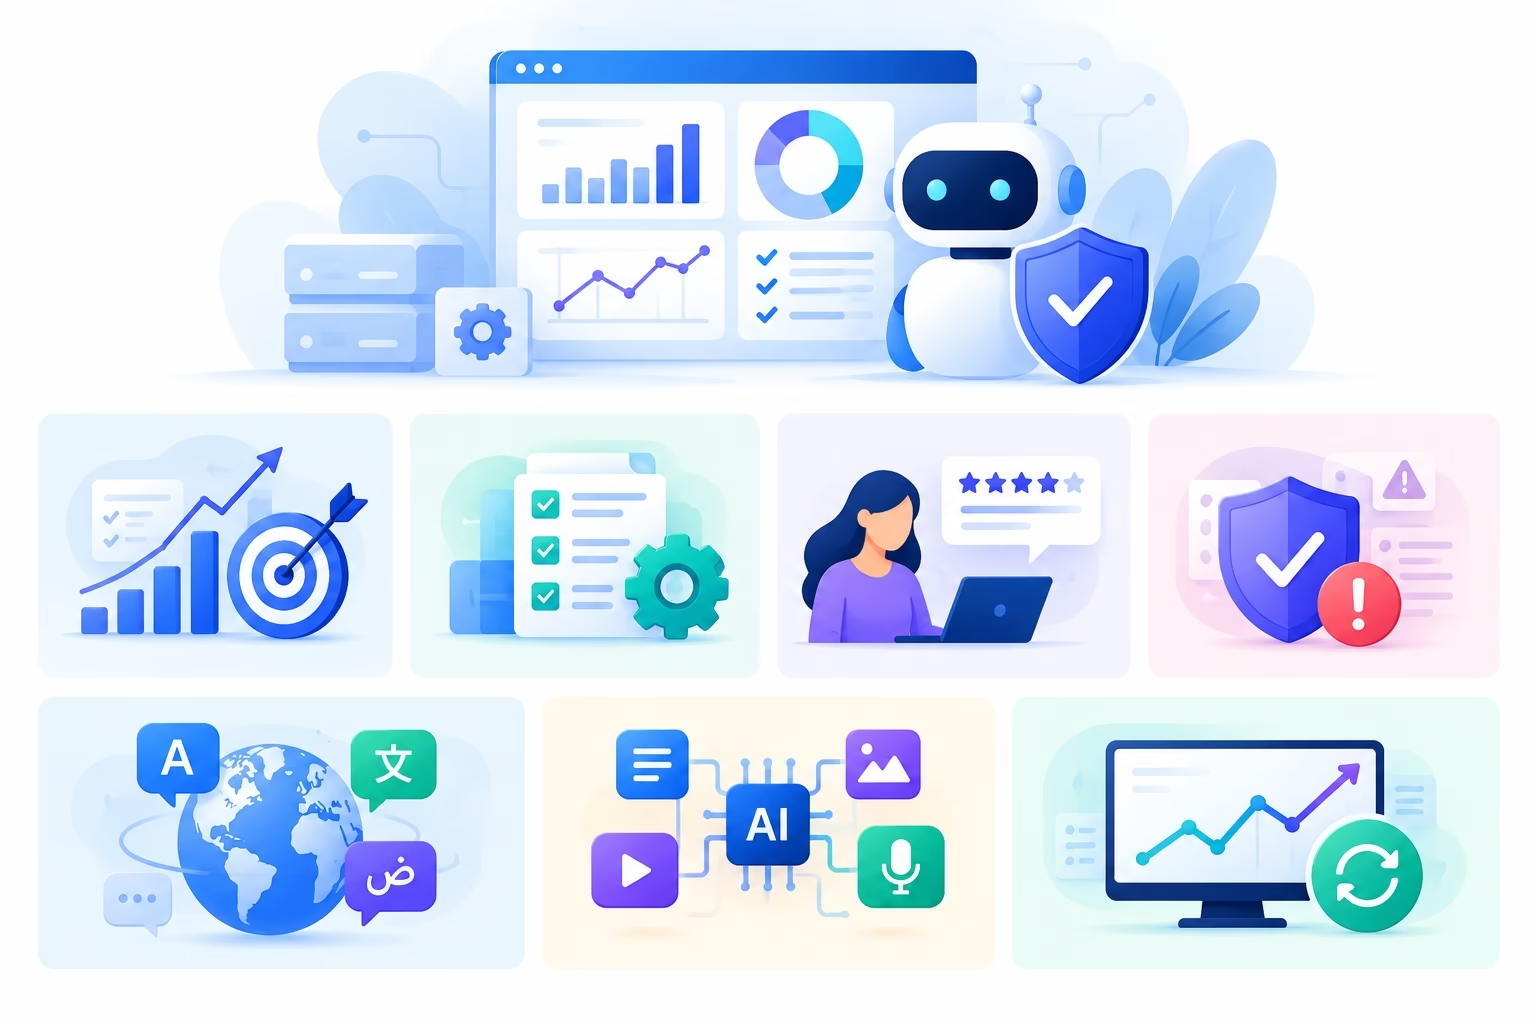
Comprehensive AI Model Evaluation
Benchmark + Performance Evaluation
Customized Evaluation
Human-in-the-Loop Evaluation

01
Safety + Bias Evaluation
Identify harmful outputs, misinformation and cultural blind spots.
02
Multilingual Evaluation
Highlight performance disparities and safety issues that English-language benchmarks may overlook.
03
Multimodal Evaluation
Evaluate AI systems across text, speech, image, video and combined modalities.
04
Continuous Evaluation
Track model performance as systems evolve. Identify changing behaviors through ongoing evaluation, expert human feedback and repeatable testing.
Experienced linguists and specialists bring language and cultural context to every project.
Support across languages, markets, and cultural environments.
Flexible workflows, CAT tools, CMS/TMS integrations, APIs, and AI-assisted translation.
Multi-stage linguistic review and QA help maintain accuracy and consistency.